
Synthetic Data vs Real Data: Building Better Robotics Training Pipelines
FAQ
Can synthetic data fully replace real-world data?

Not entirely. Synthetic data can provide substantial training coverage for some tasks. Real-world data remains essential for capturing physical conditions, uncovering unexpected failures, and validating deployment performance.
How much real data do we need?
There is no universal number. It depends on the task, hardware, environment, and model. Focus on whether the data covers the situations where the robot currently struggles.
What is the sim-to-real gap?
It is the difference between performance in simulation and on physical hardware, often caused by differences in sensing, dynamics, actuation, timing, and environmental conditions. Test transfer on physical hardware; visual realism alone does not establish that a simulated task behaves correctly.
It is the difference between a robot’s performance in simulation and on physical hardware, often caused by differences in sensing, dynamics, actuation, timing, and environmental conditions. To assess whether a policy will work in the real world, we test it on physical hardware across representative conditions and edge cases, and then compare the results with its performance in simulation. This is because visual realism alone does not guarantee reliable real-world performance.
When should physical collection complement simulation?
Physical collection should complement simulation when teams need to validate simulated assumptions, expand coverage of unfamiliar conditions, or investigate failures observed in deployment. Real-world data helps establish which scenarios matter, while simulation can generate controlled variations around them. Using both allows teams to test transfer to physical hardware and improve training coverage without relying on either source alone.
How is synthetic data validated?
Compare its scenarios, labels, and model performance against carefully selected real-world data. Check whether it represents the conditions and failure modes relevant to deployment.
Match Your Training Data to Your Robot's Needs
Discover more
GPT-4o-mini vs SEA-LIONv3: Bahasa Indonesia LLM Evaluation
A 50-task study tested Indonesian-specific prompts in English and Bahasa Indonesia to examine how model preferences varied across local-context tasks.
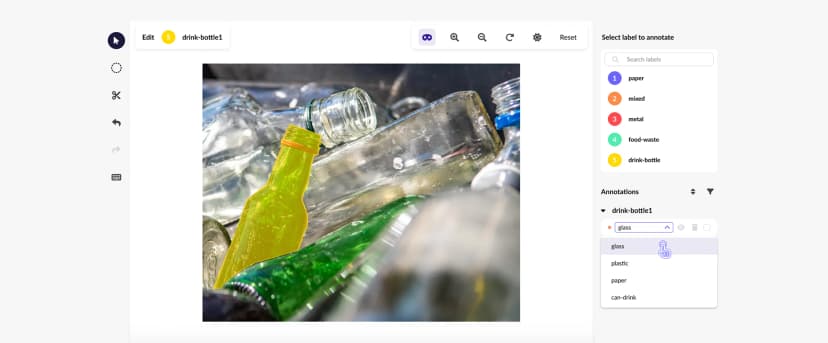
What Is Data Labeling? A Comprehensive Guide
Without properly labeled data, ML models struggle to understand key features, leading to unreliable results. This guide explores what data labeling is, how it works, different approaches, best practices, and its real-world applications.
SEA-LIONv3 vs SahabatAI-v1: Bahasa Indonesia LLM Evaluation
SEA-LIONv3 and SahabatAI-v1 were tested on 50 Indonesian-specific tasks to examine how model preferences changed across task categories and prompt languages.