
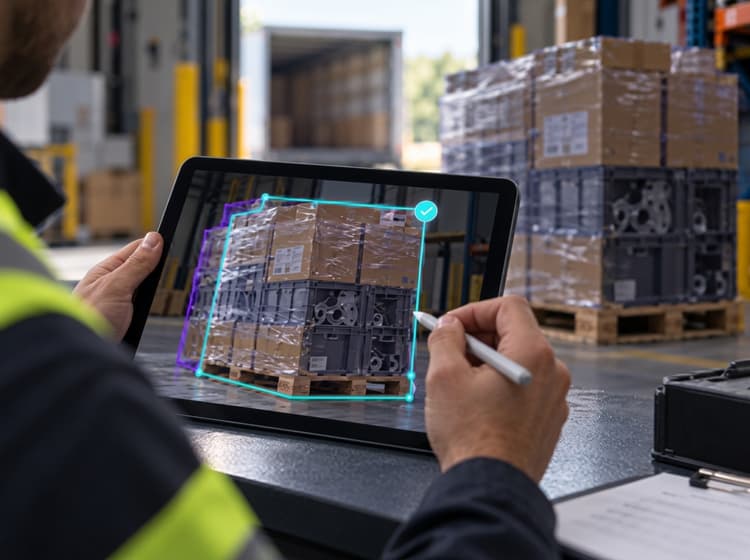
Keep annotation quality consistent as work scales
As annotation work scales, reviewers can interpret the same guideline differently. Specialist tasks will require domain judgment. Chemin’s stringent standards and project management teams ensure these errors are addressed before scaling.
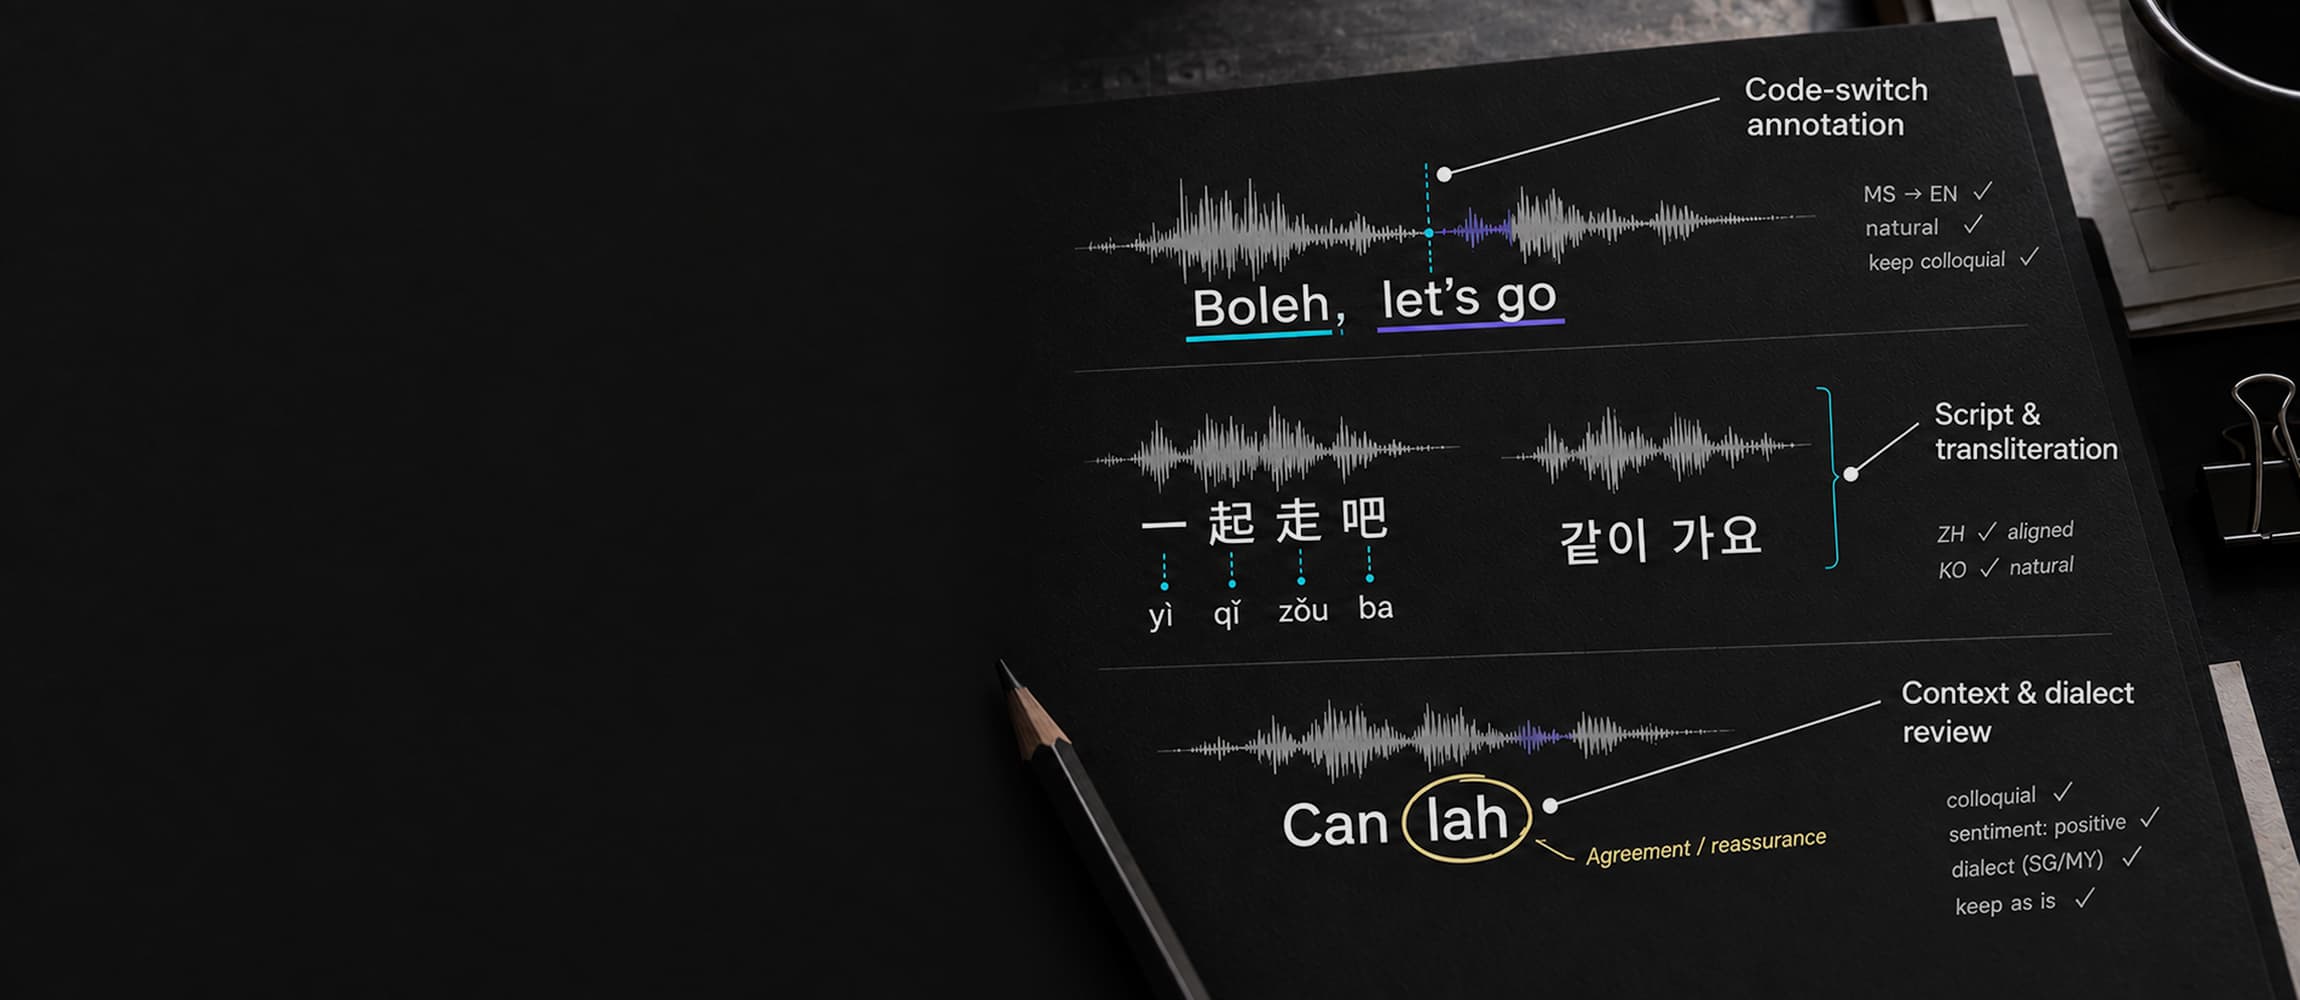
Task-specific rubrics
Define labeling criteria with your ML and domain teams before work begins.
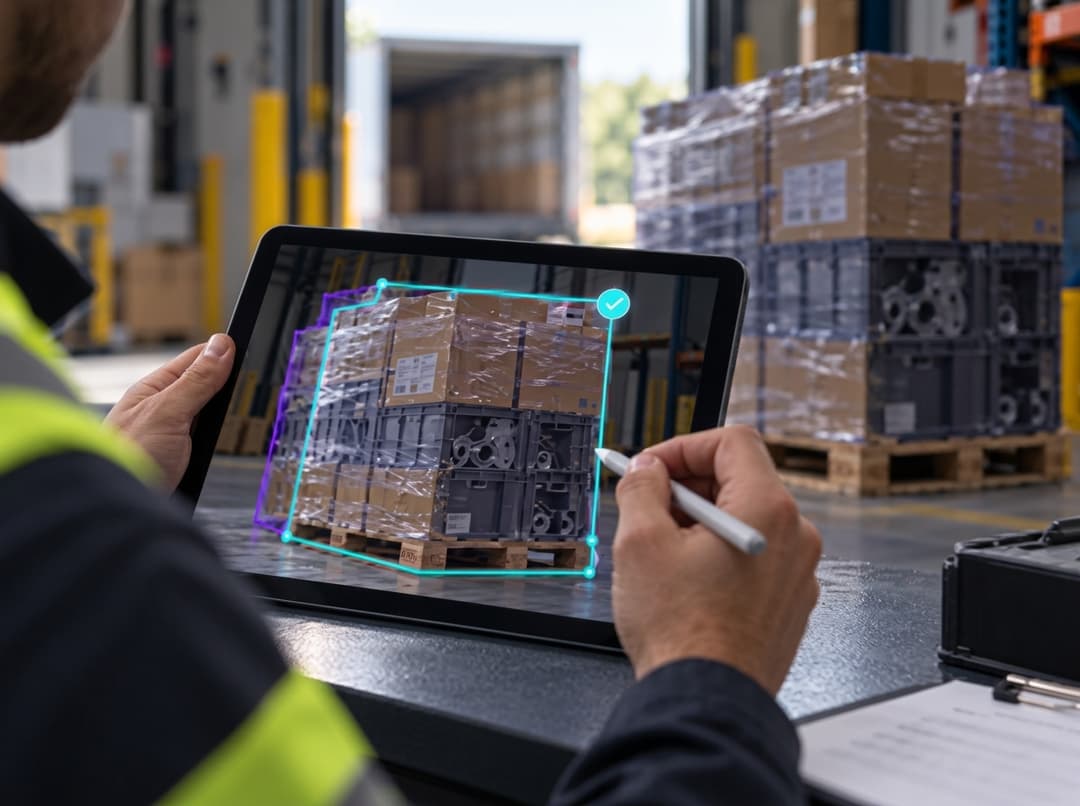
Keep annotation quality consistent as work scales
As annotation work scales, reviewers can interpret the same guideline differently. Specialist tasks will require domain judgment. Chemin’s stringent standards and project management teams ensure these errors are addressed before scaling.
Task-specific rubrics
Define labeling criteria with your ML and domain teams before work begins.
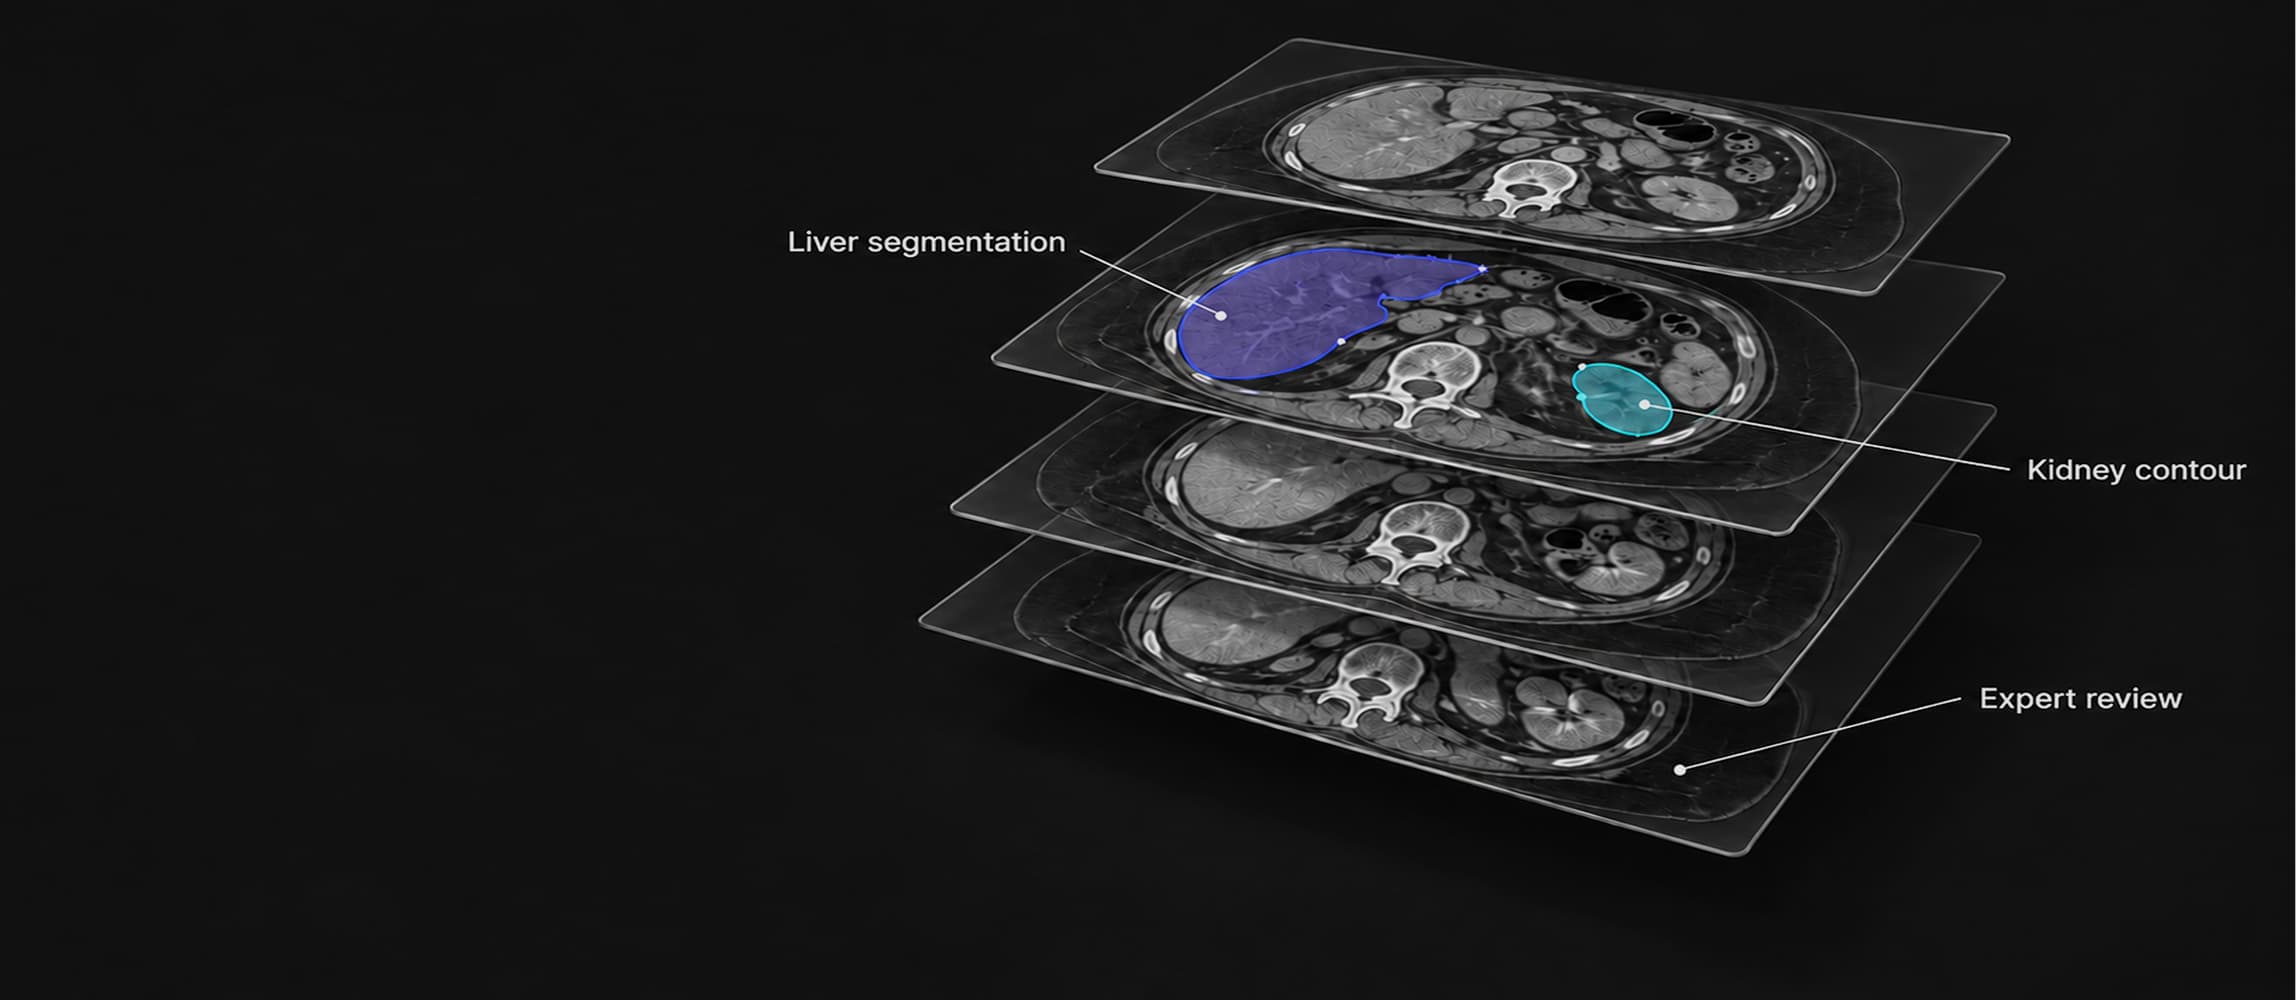
Specialist review
Match tasks to reviewers with relevant subject expertise.
Pre-annotation workflows
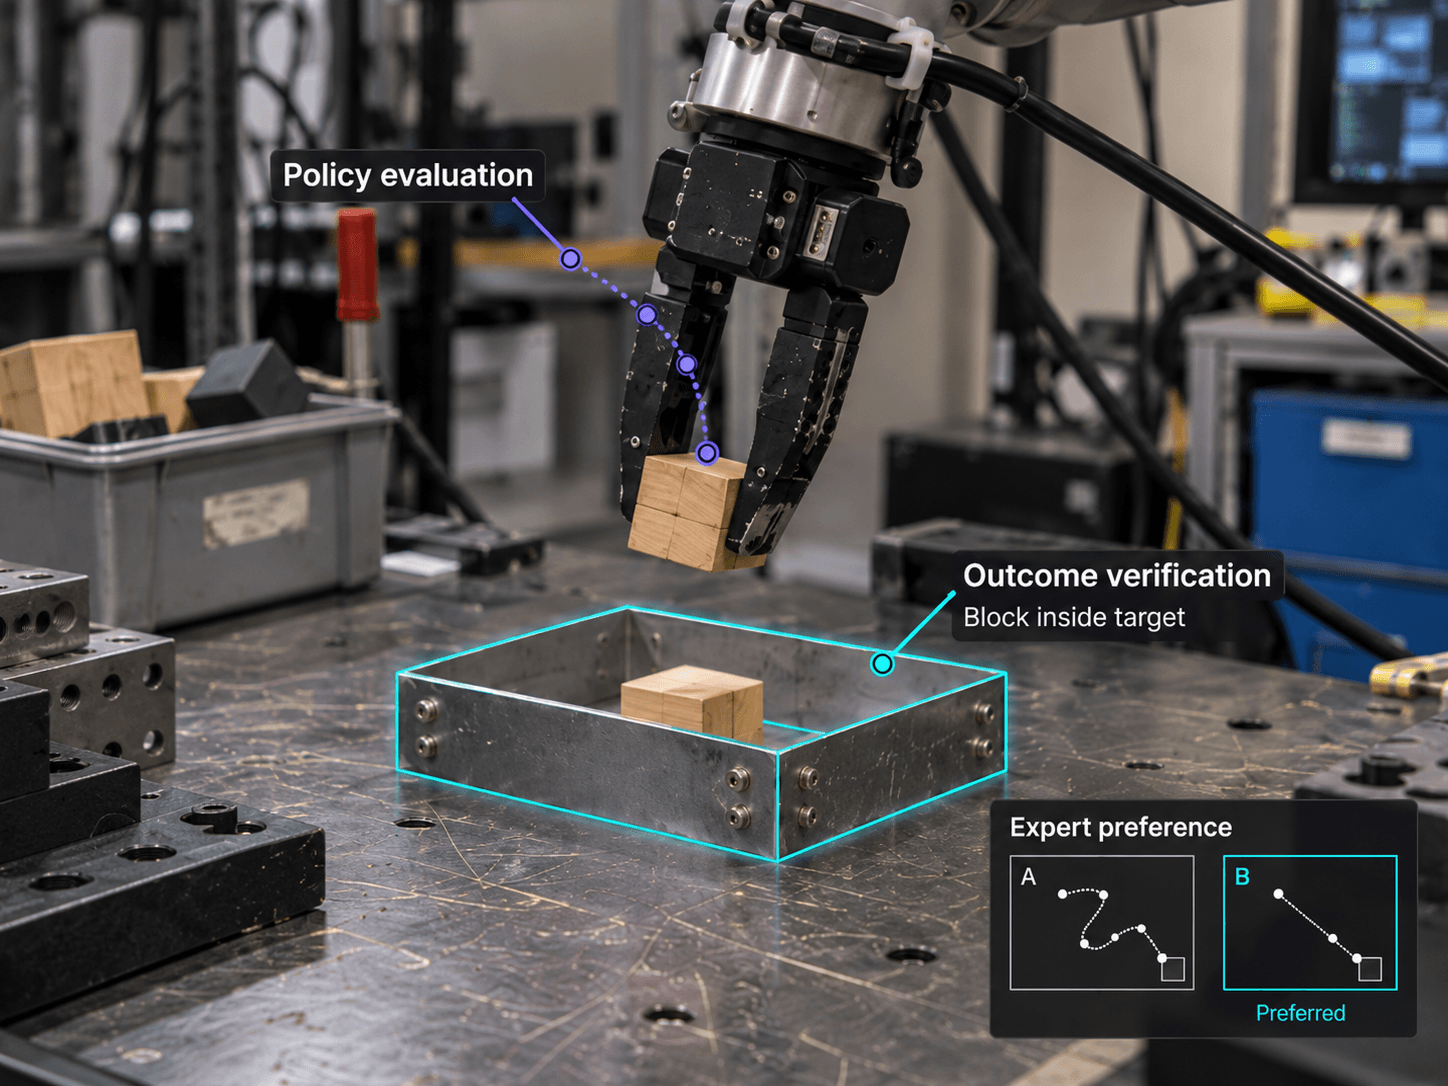
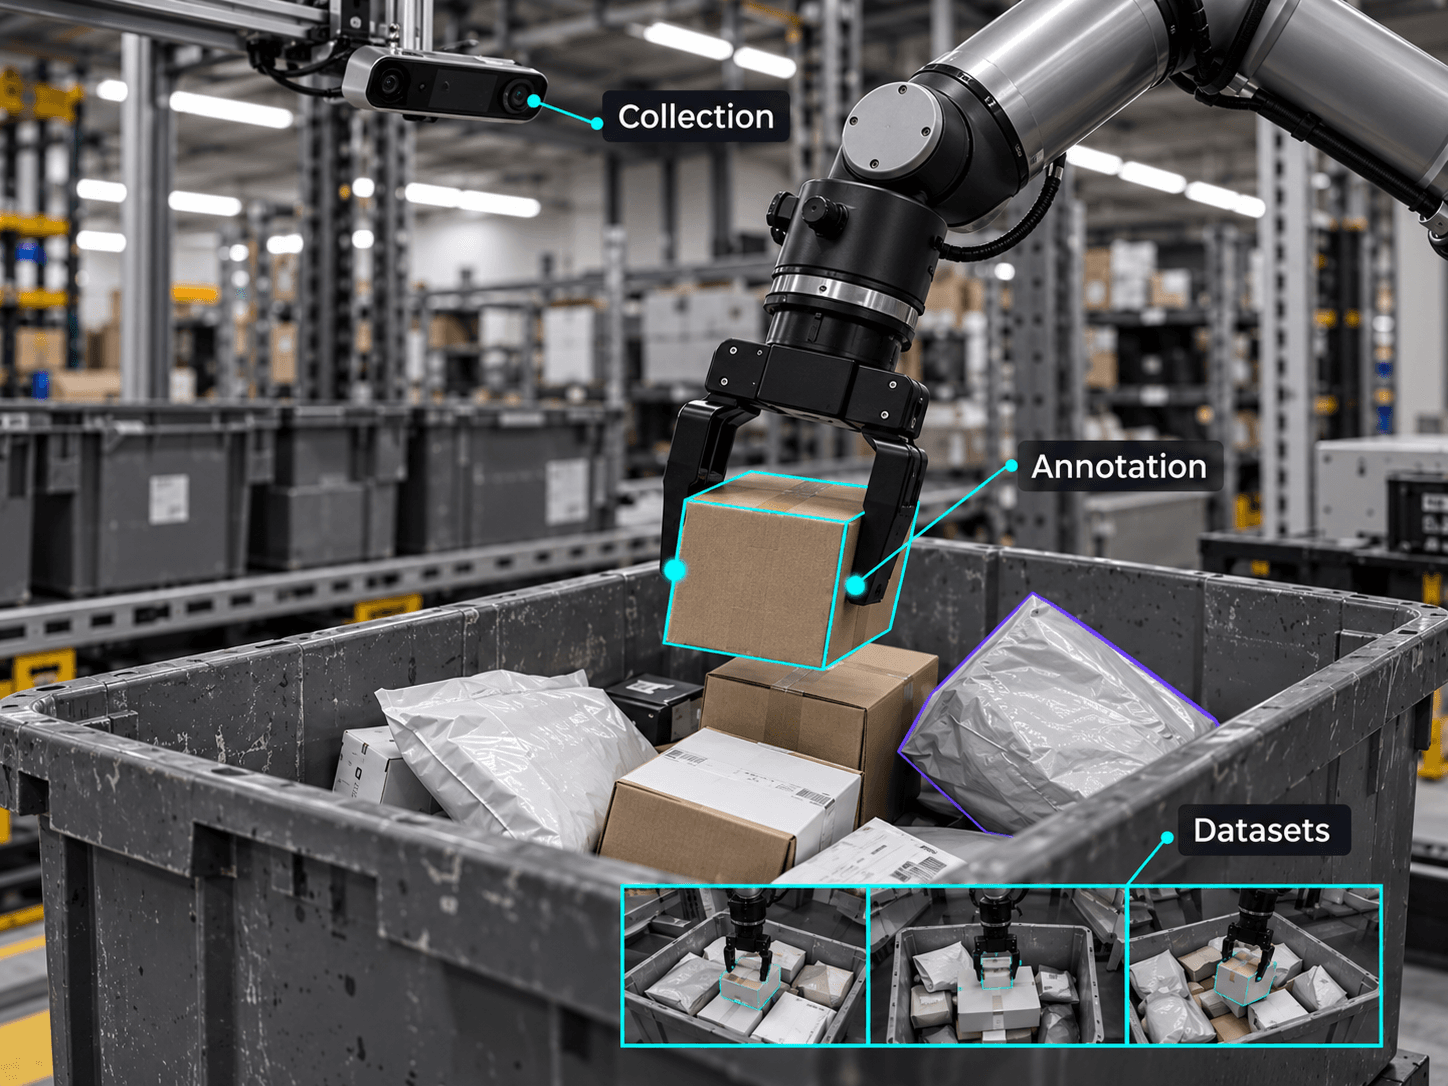
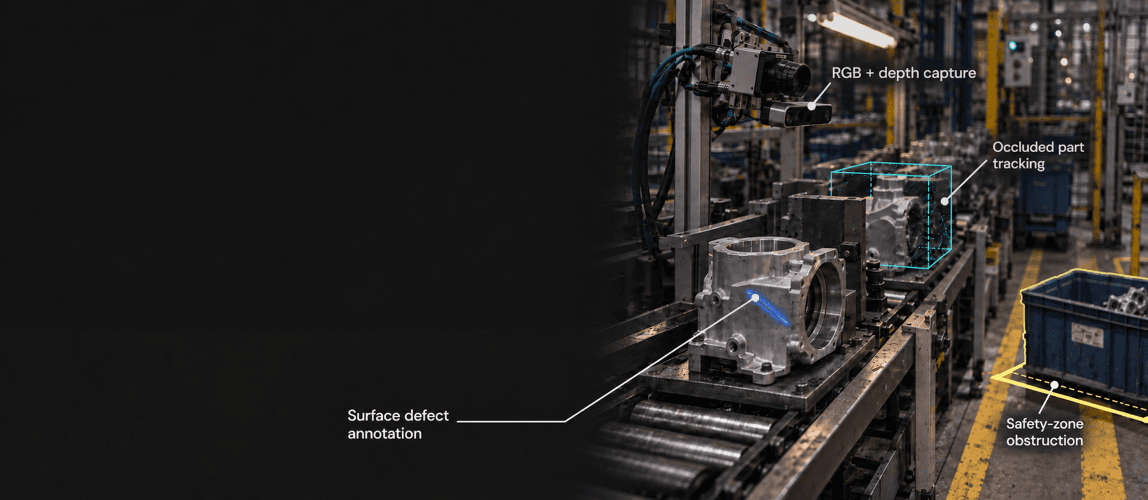
For suitable high-volume projects, reviewers check and correct model-assisted labels before delivery.
Quality reporting
Track gold-standard checks and annotator agreement as work progresses.
The challenges that hold back annotation programs
Holding Quality Steady At Scale
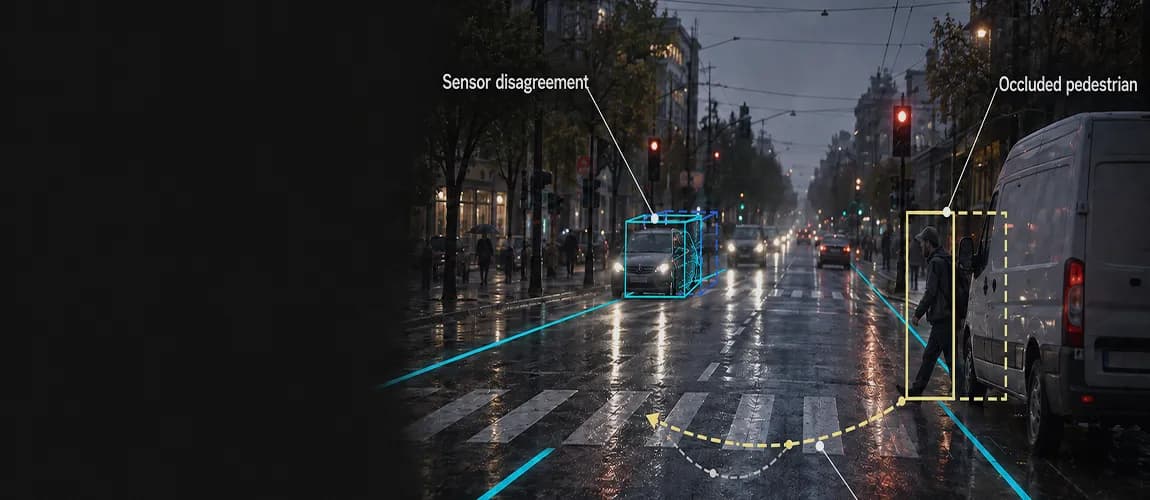
Studies of annotation error in perception systems find failures accumulate into recurring patterns, which means quality has to be engineered, not assumed.
Rubric Drift As The Pool Grows
A rubric clear to a small team gets read inconsistently across dozens of annotators, producing a dataset labeled to a slightly different standard each week.
Domain Expertise For Hard Tasks
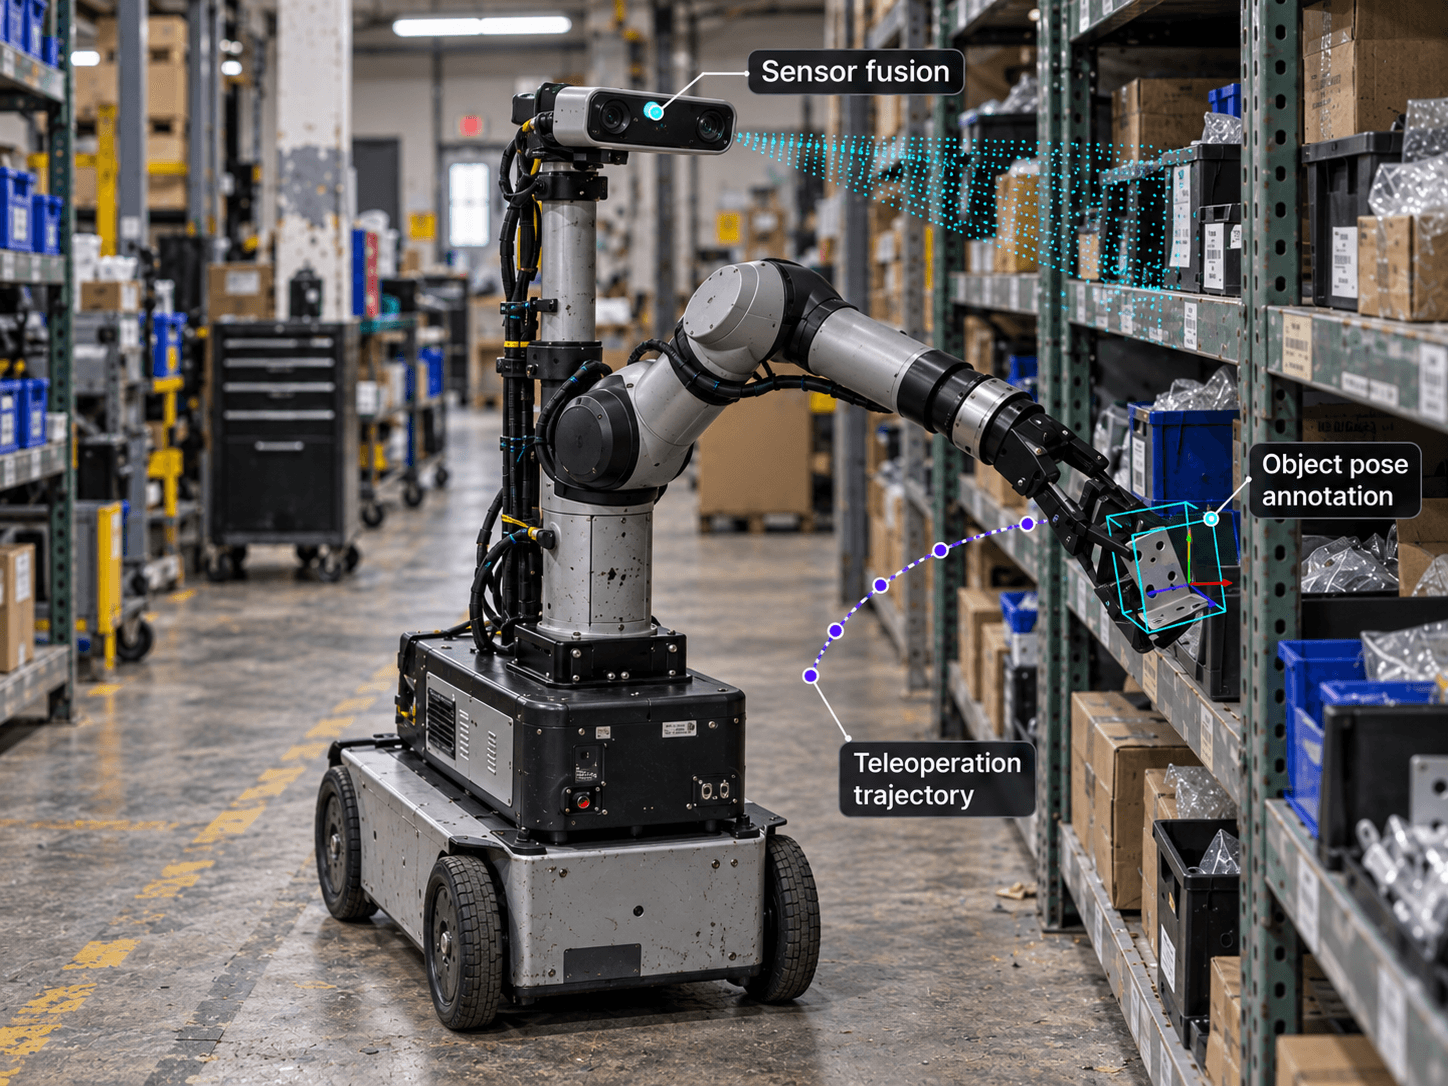
Reading a sensor-fusion scene or a clinical note takes judgment a general-purpose annotator was never trained for, producing labels that are wrong in hard-to-catch ways.
Data generation from source to success
End-to-end data services from sourcing and annotation to data generation for model training
100M+
30,000+
18
Data generation from source to success
End-to-end data services from sourcing and annotation to data generation for model training
100M+
30,000+
18
Why Chemin
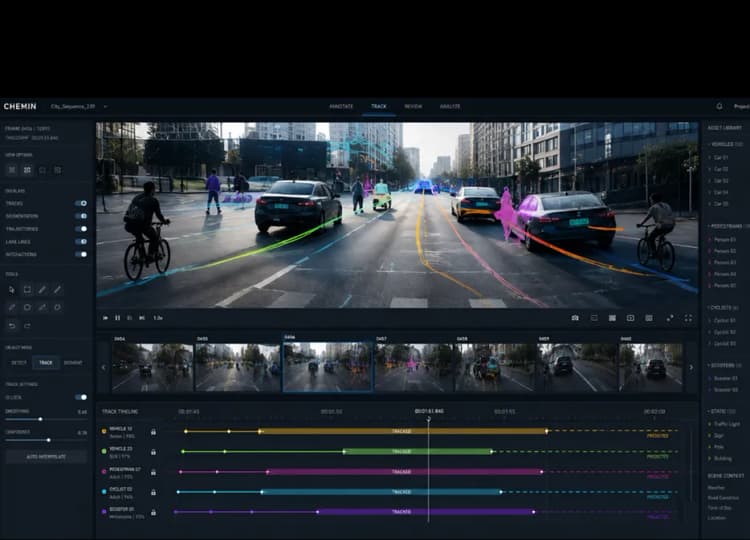
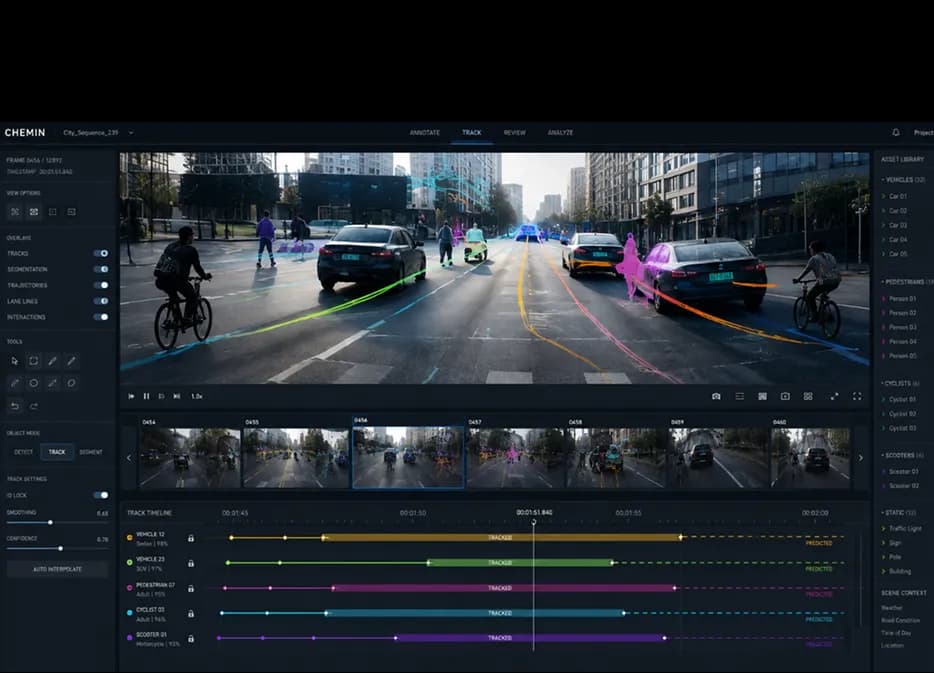
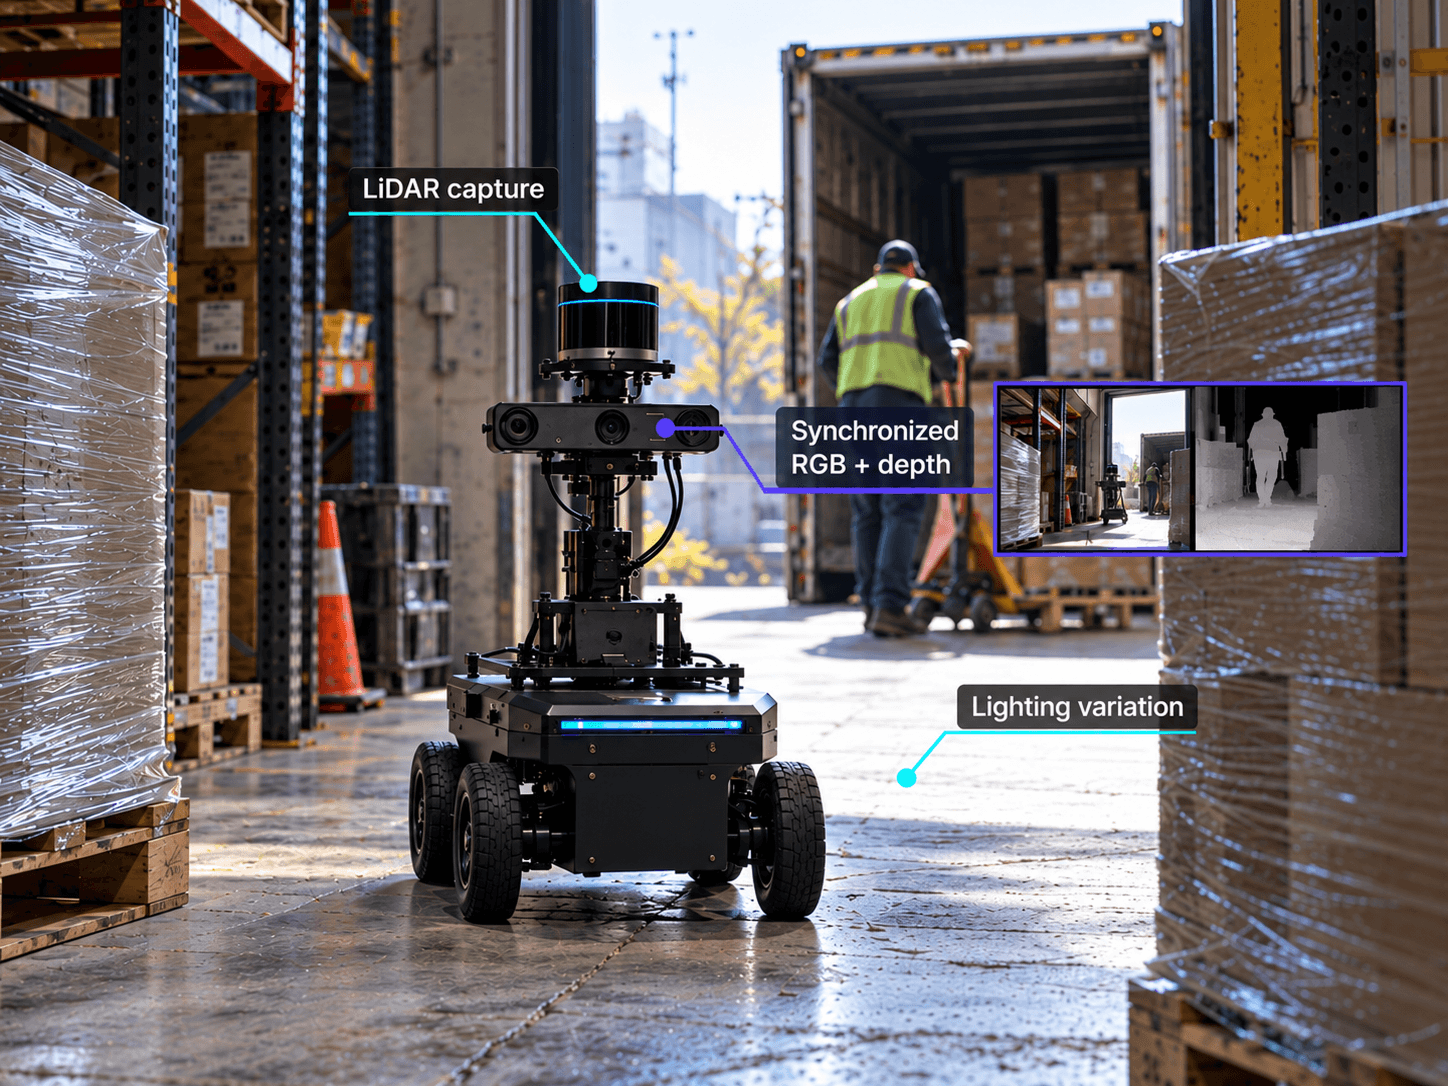
Our team includes 50+ specialists in LLM and data engineering, backed by more than 25 years of enterprise delivery experience and over 100 million data points processed. We label text, image, video, audio, and multi-sensor data including LiDAR. Rubrics are built together with your ML and domain teams before labeling starts. For high-volume projects, we also run pre-annotation workflows, where an initial pass of model-assisted labels is generated and then reviewed and corrected by human annotators, which speeds up throughput without skipping human review. Every project is checked against gold-standard QA and inter-annotator agreement, tracked and reported as we go. Work is matched to a domain specialist workforce based on task complexity, and delivery is backed by clear SLAs with transparent throughput reporting.
Why Chemin
Our team includes 50+ specialists in LLM and data engineering, backed by more than 25 years of enterprise delivery experience and over 100 million data points processed. We label text, image, video, audio, and multi-sensor data including LiDAR. Rubrics are built together with your ML and domain teams before labeling starts. For high-volume projects, we also run pre-annotation workflows, where an initial pass of model-assisted labels is generated and then reviewed and corrected by human annotators, which speeds up throughput without skipping human review. Every project is checked against gold-standard QA and inter-annotator agreement, tracked and reported as we go. Work is matched to a domain specialist workforce based on task complexity, and delivery is backed by clear SLAs with transparent throughput reporting.
Frequently asked questions
Find answers to common questions about our services, process, and how we can support your needs.
Which data types can Chemin annotate?

Chemin annotates text, image, video, audio, and multi-sensor data, including LiDAR. Project scope is defined around the modalities your model uses.
How is annotation quality measured?
Chemin's quality checks can include comparisons against gold-standard reference labels and measures of agreement between annotators. We select the checks around your task and report the results as work progresses.
Can Chemin use our existing guidelines?
Yes. The team can adapt existing guidelines or develop task-specific criteria with you before labeling begins.
Can you review partially labeled data?
Yes. Existing annotations can be reviewed, inconsistencies corrected, and partially labeled datasets extended to the agreed requirements.
Does Chemin use AI-assisted pre-annotation?
For suitable projects, model-generated labels can provide an initial pass. Human reviewers validate and correct them before delivery.
Put your annotation criteria to the test
Review a sample dataset labeled to your project's criteria before discussing the next batch.