
Seven Questions Before Choosing a Teleoperation Vendor
Introduction
As robotics teams move from lab demonstrations to production systems, the constraint has shifted. For a long time, progress was gated by model architecture. Today it is gated by data. Training a robot to manipulate the physical world requires examples of that manipulation, and the most reliable way to generate them at present is teleoperation, or teleops.
That demand has pulled a wave of new teleops vendors into the market, all offering to run robot data collection on your behalf. The difficulty for a buyer is that the quality difference between a strong vendor and a weak one is largely invisible at the point of sale. Two providers can quote the same number of demonstrations in the same format, and only one of the datasets will train a policy that works. The gap usually does not surface until a model underperforms in evaluation and no one can explain why.
The good news is that the robot-learning literature is unusually clear about which properties of a dataset actually predict policy performance. Those properties map directly onto questions you can ask a vendor before you sign. Use them in a first call, or drop them straight into an RFP for a teleops data vendor. The seven below are ordered from the easiest to verify to the most revealing.
Executive Summary
- Teleoperation data, often shortened to teleops, is a record of a human remotely guiding a robot through a task, and it has become the dominant training signal for physical AI as demand outstrips reliable supply.
- The quality gap between vendors is wide and hard to see from a pitch deck, because the failures that matter, such as incomplete grasps, sensor sync drift and thin scenario coverage, are invisible to a general reviewer.
- Research consistently shows that curation and coverage, not raw demonstration count, decide whether a dataset trains a working policy. In recent work, removing low-quality episodes lifted real-robot success rates by up to 30 points.
- This guide sets out seven evidence-based questions, from hardware ownership to operator qualification, that let you assess a teleoperation vendor before you commit.
What is teleoperation data?
What is it? Teleoperation data, commonly shortened to teleops, is a record of a human operator remotely controlling a robot to complete a task. Each demonstration, or episode, captures a synchronised stream of what the robot sensed and did: camera views, joint positions, gripper forces and the operator’s commands, all timestamped together. Teleops sits at the centre of robot data collection for physical AI.
Why does it matter? Physical AI models learn manipulation by imitating these demonstrations. Unlike text and images, action-paired sensorimotor data does not exist at web scale, so it has to be generated deliberately, one episode at a time. That makes the quality of the data a direct input to how well the resulting model performs.
Where is it used? Teleoperation data trains vision-language-action models and imitation-learning policies for robotic manipulation, spanning humanoids, bimanual arms, and warehouse and industrial robots. Widely cited research systems, including ACT from the ALOHA project, OpenVLA and Pi0, achieve their strongest results when trained on high-quality teleoperated demonstrations.
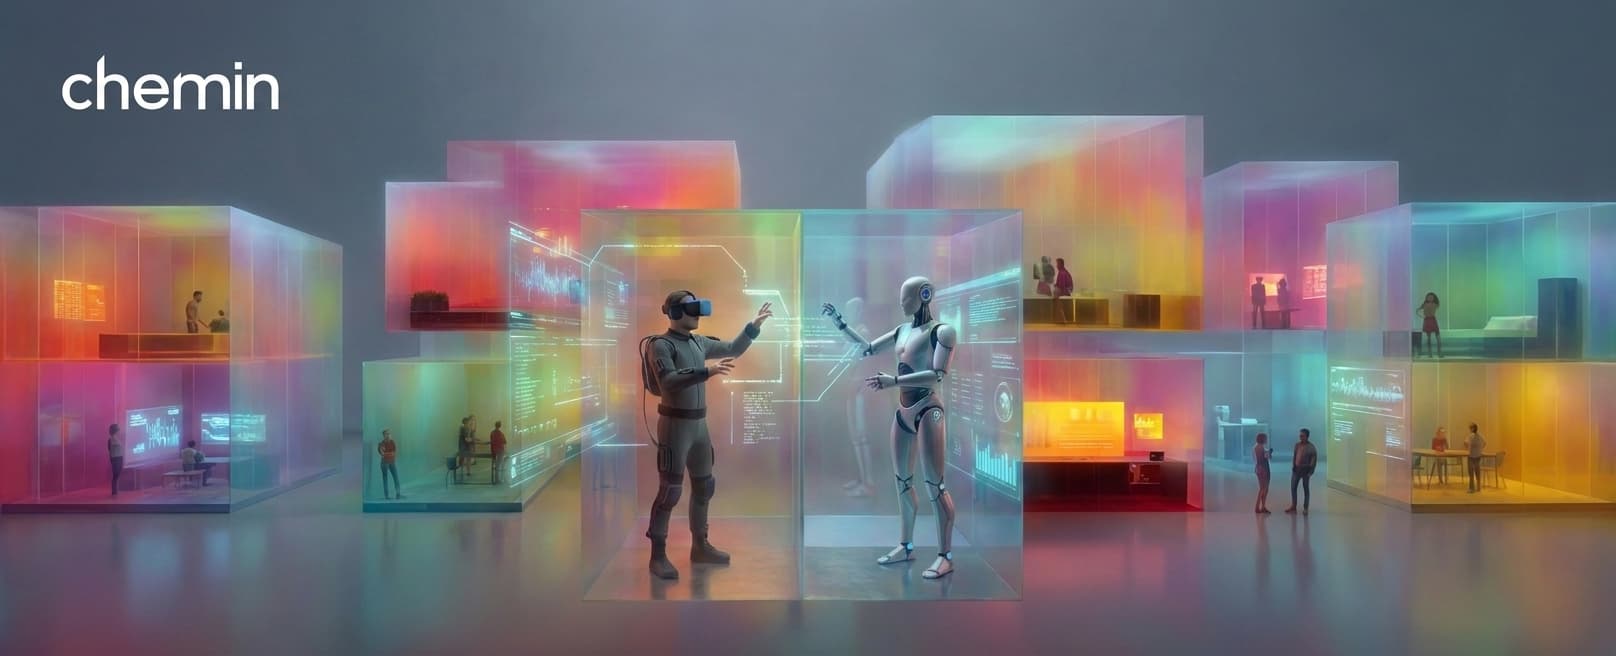
Figure 1. Visual illustration of teleops in action

The seven questions to ask a teleops vendor
1. Do you own and calibrate your own collection hardware?
A vendor that does not own its collection rigs cannot control calibration consistency across sessions, cannot troubleshoot equipment failures without waiting on a third party, and cannot guarantee that hardware specifications match across a dataset. Small inconsistencies in camera placement or calibration become noise that a model can misread as signal. Rented rigs rarely come up in a pitch unprompted, which is exactly why this is worth asking first.
This is why the field’s reference datasets treat calibration as part of the data itself. DROID, a large in-the-wild manipulation dataset, stores camera calibration alongside three synchronised RGB streams and depth for every episode. Calibration is shipped as part of the data contract, not assumed after the fact.
What a strong answer sounds like: named hardware, owned outright, a calibration routine the vendor can describe, and calibration data delivered with the episodes.
2. Who does your quality assurance, and what do they know about robots?
If you only have time to probe one answer properly, make it this one.
Robot manipulation demonstrations fail in ways that are invisible to a general reviewer but obvious to someone who understands robot kinematics. A reviewer who has spent years drawing bounding boxes will happily pass an episode that a robotics engineer would reject in seconds. Same video, different eyes, very different dataset.
The evidence here is worth slowing down for, because it changes how much weight you give every other question.
Evidence. Research on teleoperation quality finds that novice operators routinely produce episodes that are task-successful but suboptimal for downstream use, through inefficient motion, repeated corrections, or operation near the robot’s joint limits (Narayanan et al., 2026, preprint). Separately, a NeurIPS study identifies action divergence and transition diversity as the two properties that govern data quality, and shows that in real human-generated datasets, less consistent actions at a given state are associated with worse policy performance (Belkhale et al., 2023).
Interpretation. A demonstration can reach the goal and still teach the model the wrong thing. Success and quality are not the same measurement, and only a reviewer who understands robot behaviour can tell them apart. A binary pass/fail check cannot.
Business implication. The value of expert quality assurance is quantifiable. In recent work on demonstration curation, removing low-quality trajectories improved real-robot success rates by up to 30 percentage points, and simulation results by up to 23 percentage points (QoQ, 2026, preprint). The same collection budget, reviewed by people who know what they are looking at, is the difference between a policy that works and one that does not.
What a strong answer sounds like: reviewers with a robotics background, in-session monitoring combined with post-session validation, per-episode quality scoring that goes beyond binary success, and a documented rejection rate the vendor is willing to share.
3. Who designs the scenarios, the operator or you?
Vendors that let operators choose their own scenarios tend to produce datasets that are heavy with duplicated easy cases and thin on the edge cases that actually determine whether a policy is robust in deployment.
This is the single most useful finding for buyers to internalise. A study on data scaling laws in imitation learning collected more than 40,000 demonstrations and ran over 15,000 real-world rollouts. It found that a policy’s ability to generalise scales approximately as a power law with the number of training environments and objects, and that the diversity of environments and objects matters far more than the absolute number of demonstrations. Past a threshold, extra demonstrations in an already-covered setting add very little (Lin et al., 2024). In one result, 32 environments, each with a unique object and 50 demonstrations, trained a policy that reached roughly 90% success on new environments and objects.
The implication is direct: a vendor quoting you on demonstration count is quoting the wrong unit. What determines model performance is coverage.
What a strong answer sounds like: a scenario script agreed before collection begins, defined object and environment counts, and deliberate coverage of edge cases rather than operator convenience.
4. What format are you delivering, and have we agreed on it in writing?
Delivery format, whether RLDS, HDF5, LeRobot format or a custom schema, should be settled before collection begins, not discovered after delivery. What you are actually buying is synchronised video, telemetry and operator commands as a single coherent stream. That combination is the highest-signal demonstration data the industry currently has.
Format is not administrative detail. It determines whether your data can be combined with anything else. RLDS was created specifically so datasets could be shared without information loss and processed independently of their original format (Ramos et al., 2021). The Open X-Embodiment collaboration pooled over one million trajectories across 22 robot embodiments from 21 institutions in a standardised format, which is what made cross-embodiment training possible in the first place (2023).
What a strong answer sounds like: a named delivery format confirmed in the contract, synchronised multi-stream episodes, and a sample delivered early so your team can load it before volume collection starts.
5. How do you handle multi-sensor synchronisation, and what is your tolerance?
Sensor sync drift is the quiet killer of a dataset, because the data still opens and still looks fine. A misalignment of a few tens of milliseconds between camera frames and joint positions corrupts the action representation the model learns from, without producing any obvious error.
The field’s most-used datasets already show what good looks like. Every DROID episode carries three synchronised RGB streams, calibration, depth and a natural-language instruction. If a widely shared academic dataset treats that as baseline, a commercial vendor should clear it comfortably.
What a strong answer sounds like: a stated synchronisation tolerance in milliseconds, and a description of how it is verified per episode rather than per session.
6. How many robot platforms have you actually collected on?
A provider that runs only one arm type can only give you limited generalisation data. Breadth is not a nice-to-have. It is a measured source of capability: the Open X-Embodiment work showed that models trained across 22 embodiments exhibited positive transfer, improving performance on individual robots by drawing on experience from other platforms (2023).
Different robots also demand genuinely different competencies. A humanoid needs dexterous manipulation with balance feedback. An autonomous vehicle needs sub-second intervention handling. A factory arm or autonomous mobile robot needs reliable handoffs between the operator and the onboard planner at millisecond tolerances. A vendor that supports only one of these is selling a custom integration, not a platform capability.
What a strong answer sounds like: demonstrated collection across multiple robot types, and honesty about which platforms they have real experience with versus which they are still learning.
7. How do you train, qualify and re-qualify operators?
Teleops data is made by people, and the skill of the person driving the robot shows up directly in the data. An experienced operator moves smoothly, recovers cleanly and stays away from joint limits. A novice moves slower, corrects more and produces less stable demonstrations. That gap is trainable: in a pilot study, the operator who received immediate, automated post-episode feedback improved faster and produced higher-quality demonstrations sooner than those who did not (Narayanan et al., 2026, preprint). How a vendor develops its operators is therefore not an HR detail. It is a data quality lever.
Remote collection is viable. The RoboTurk platform gathered 137.5 hours and over 2,200 successful demonstrations through crowdsourced remote teleoperation, and found that poor network conditions did not substantially impair operators’ ability to complete tasks (Mandlekar et al., 2018). But the follow-on work that aggregated more than 60,000 trajectories still contained suboptimal ones, which is precisely why qualification and quality assurance matter more at scale, not less. Latency is worth checking directly, since communication-delay studies report measurable performance degradation at 200 to 300 milliseconds (2025).
What a strong answer sounds like: documented per-operator qualification, session-length limits, automated per-episode scoring, a defined feedback loop, and a re-qualification cadence.
Figure 2. Illustration showcasing the summary of the teleops process
Expert Perspective
Across these seven questions, one pattern holds: the hard part of teleoperation is not capturing demonstrations, it is knowing which ones to keep. Teams that evaluate vendors on price per demonstration are measuring the cheapest input, not the one that determines model performance. In practice, the vendors worth signing are the ones who can tell you why a specific episode was rejected. If a provider cannot answer that, they are recording, not curating, and the difference will show up in your evaluation numbers rather than your invoice.
Key Takeaways
- Teleoperation data quality is decided by curation and coverage, not by demonstration volume. Budgeting by demonstration count optimises the wrong variable.
- The failure modes that ruin a dataset, such as incomplete grasps and sensor sync drift, are invisible to a general reviewer, which makes domain-expert quality assurance the single most important thing to evaluate in a vendor.
- Scenario coverage across diverse environments and objects predicts generalisation more strongly than the number of demonstrations, so ask for the coverage plan, not just the headcount.
- Hardware ownership, agreed delivery formats and multi-sensor synchronisation are verifiable before you sign, and a vendor’s answers reveal how much of the pipeline they genuinely control.
- The most reliable single test of a teleops vendor is whether they can explain why an episode was rejected.
Sources & References
Peer-reviewed sources:
- Belkhale, S. et al. (2023). Data Quality in Imitation Learning. NeurIPS. arXiv:2306.02437
- Mandlekar, A. et al. (2021). What Matters in Learning from Offline Human Demonstrations for Robot Manipulation. CoRL. arXiv:2108.03298
- Khazatsky, A., Pertsch, K. et al. (2024). DROID: A Large-Scale In-The-Wild Robot Manipulation Dataset. arXiv:2403.12945
- Open X-Embodiment Collaboration (2023). Open X-Embodiment: Robotic Learning Datasets and RT-X Models. arXiv:2310.08864
- Zhao, T. Z. et al. (2023). Learning Fine-Grained Bimanual Manipulation with Low-Cost Hardware (ALOHA / ACT). arXiv:2304.13705
- Mandlekar, A. et al. (2018). RoboTurk: A Crowdsourcing Platform for Robotic Skill Learning through Imitation. CoRL. arXiv:1811.02790
- Ramos, S. et al. (2021). RLDS: an Ecosystem to Generate, Share and Use Datasets in Reinforcement Learning. arXiv:2111.02767
Preprints (not yet peer-reviewed at time of writing):
- Quality over Quantity: Demonstration Curation via Influence Functions for Data-Centric Robot Learning (2026). arXiv:2603.09056
- Narayanan, G. et al. (2026). Closing the Loop in Teleoperation: Episode-Level Data Quality Assessment and Feedback for High-Quality Demonstration Collection. arXiv:2605.26349
- Lin, F. et al. (2024). Data Scaling Laws in Imitation Learning for Robotic Manipulation. arXiv:2410.18647
- The Effects of Communication Delay on Human Performance in Mobile Robot Teleoperation (2025). arXiv:2508.18074
Scoping a Teleops Programme?
Frequently Asked Questions
What is the difference between teleops and teleoperation? There is no difference in meaning. Teleops is simply the common shorthand for teleoperation, the practice of a human remotely controlling a robot. In a robot data collection context, both terms refer to generating demonstrations that train physical AI models. You will see teleops used more often in informal and commercial settings, and teleoperation in academic papers and technical documentation.
What is teleoperation data used for in robotics? Teleoperation data trains robots to manipulate the physical world. A human remotely controls a robot through a task, and the synchronised record of sensor inputs and actions becomes a demonstration that imitation-learning and vision-language-action models learn from. It is currently the dominant way to generate the action-paired data that physical AI requires.
How many demonstrations do I need to train a robot policy? It depends far more on coverage than on a single number. Research on data scaling laws found that diversity of environments and objects matters more than raw demonstration count, and that beyond a threshold, additional demonstrations in the same setting add little. A useful rule of thumb is to plan by the number of distinct environments and objects you need represented, then set a demonstration target per setting.
Should I run teleops data collection in-house or use a vendor? Both can be right. In-house robot data collection tends to win when volume is high, the task set is stable, and you already have access to the environments that matter. A teleops vendor tends to win when demand is spiky, coverage breadth is hard to build, or domain-expert quality assurance is difficult to staff internally. Our companion guide works through this decision in detail.
What is the most important thing to check in a teleops vendor? Whether they can tell you why a specific episode was rejected. Robot demonstrations fail in ways a general reviewer cannot see, so the presence of domain-expert quality assurance, with per-episode scoring and a documented rejection rate, is the strongest single signal that a vendor delivers training-ready data rather than data that merely looks complete.
Does more teleoperation data always improve model performance? No. Beyond a coverage threshold, additional demonstrations in settings the dataset already represents deliver diminishing returns, and low-quality demonstrations can actively degrade a policy. Recent work shows that curating out poor demonstrations can improve real-robot success substantially. Quality and coverage, not volume alone, drive performance.
Discover more
GPT-4o-mini vs SEA-LIONv3: Bahasa Indonesia LLM Evaluation
A 50-task study tested Indonesian-specific prompts in English and Bahasa Indonesia to examine how model preferences varied across local-context tasks.
What Is Data Labeling? A Comprehensive Guide
Without properly labeled data, ML models struggle to understand key features, leading to unreliable results. This guide explores what data labeling is, how it works, different approaches, best practices, and its real-world applications.
SEA-LIONv3 vs SahabatAI-v1: Bahasa Indonesia LLM Evaluation
SEA-LIONv3 and SahabatAI-v1 were tested on 50 Indonesian-specific tasks to examine how model preferences changed across task categories and prompt languages.